Site Reliability Engineer resume examples and templates
An SRE resume needs enough detail to distinguish an objective from measured reliability and an incident story from a trend. Show the user-facing indicator, the operational decision and the evidence that a change was tested. This fictional US example follows a scheduling service through alert review, incident learning and a recovery rehearsal, with full text beside the design previews.
These previews use the same layouts as the builder, with identical example content. Open a full preview to inspect the text and spacing.
Fictional candidate, employers, education and results. The optional portrait is AI-generated. Use your own evidence and photo; the example is not inserted into your resume.
Harbor
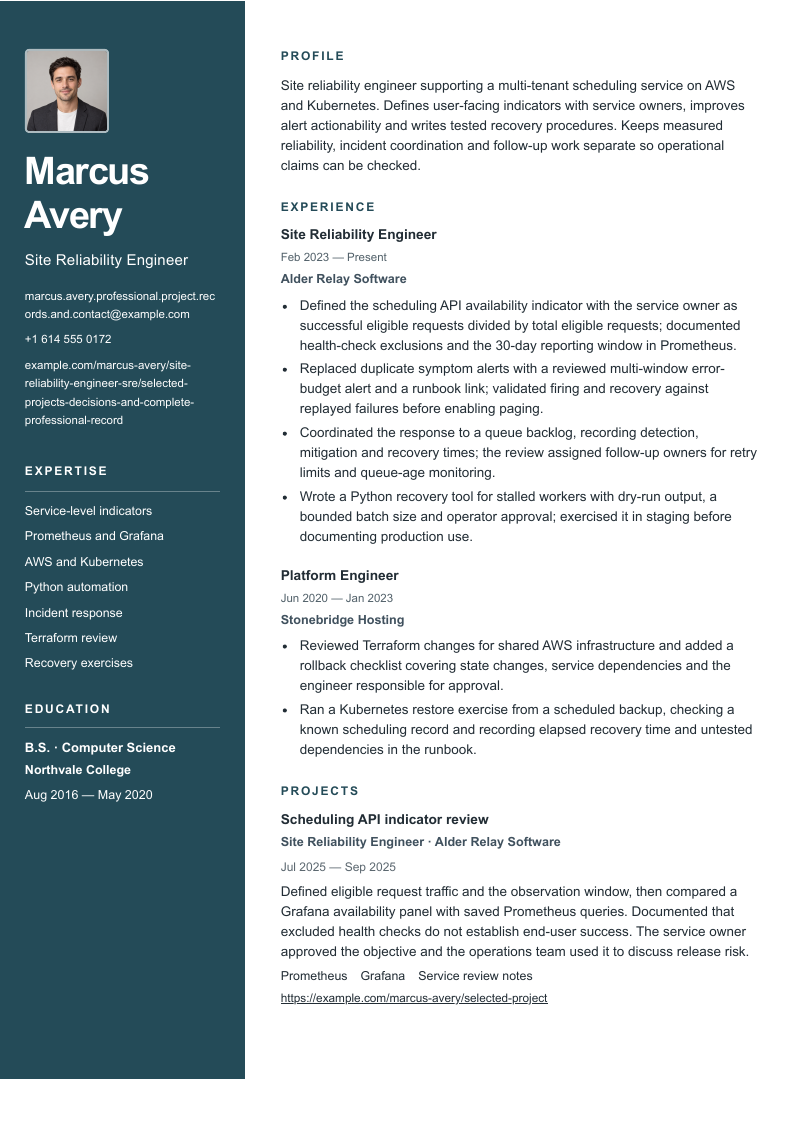
A dark left identity rail holds contact details and qualifications while a white main column carries profile, experience and projects.
Before sending: Long contact and qualification text can extend the dark rail; check the main-column continuation and text order.
“Use” opens signup with that design and photo preference selected for the builder. A free account is required. Free-plan PDF downloads include a watermark; see current plans for paid options. Photo conventions vary; follow the employer’s instructions and local expectations.
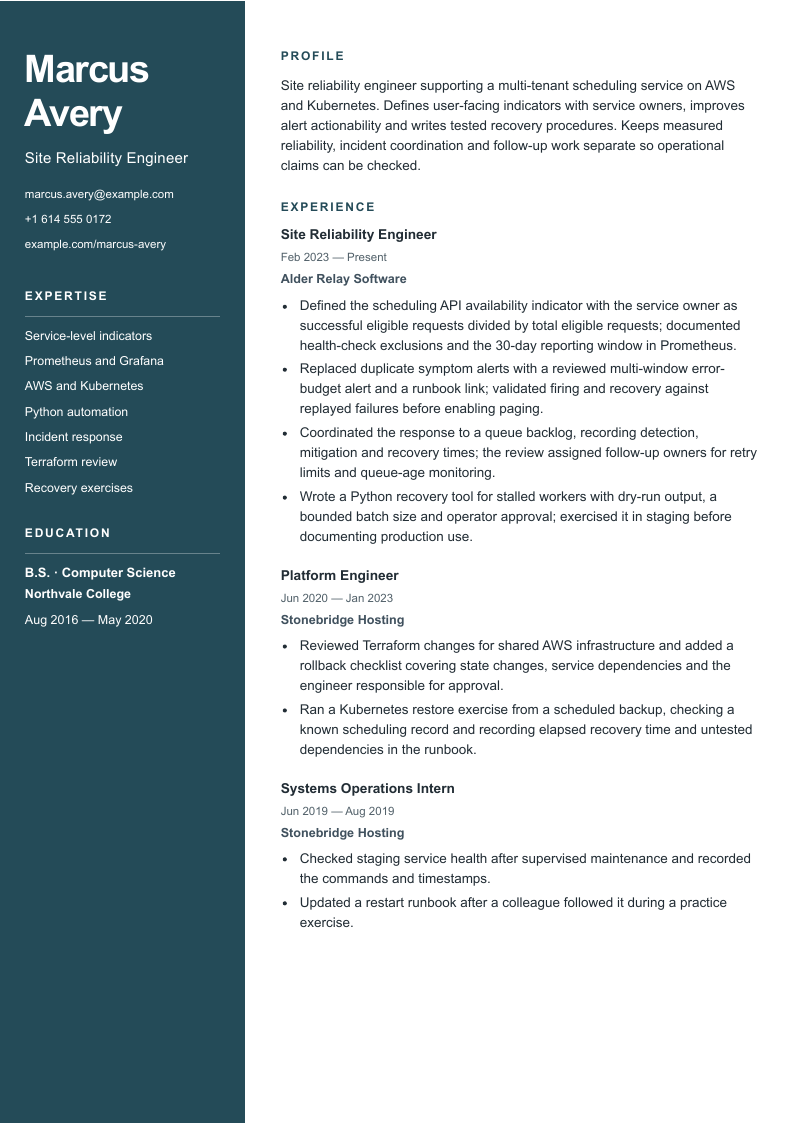
Harbor, Signal and Essential show the same Marcus Avery record. Compare every page with the optional photo on and off. No photo is selected by default. The fictional portrait demonstrates placement and is not added to your resume.
Choose the design after deciding which evidence matters. The previews are layout examples, not a parsing guarantee or a promise of interviews. Follow the employer’s requested file format and check the exported document with your own content.
Complete fictional site reliability engineer resume
All names, employers, qualifications, projects and results in this example are original editorial fiction. The two jobs contain the same six after-bullets explained below: four in the current role and two in the earlier role. The degree and selected project provide proportionate context. Replace the entire record with your own evidence.
Site reliability engineer supporting a multi-tenant scheduling service on AWS and Kubernetes. Defines user-facing indicators with service owners, improves alert actionability and writes tested recovery procedures. Keeps measured reliability, incident coordination and follow-up work separate so operational claims can be checked.
Defined the scheduling API availability indicator with the service owner as successful eligible requests divided by total eligible requests; documented health-check exclusions and the 30-day reporting window in Prometheus.
Replaced duplicate symptom alerts with a reviewed multi-window error-budget alert and a runbook link; validated firing and recovery against replayed failures before enabling paging.
Coordinated the response to a queue backlog, recording detection, mitigation and recovery times; the review assigned follow-up owners for retry limits and queue-age monitoring.
Wrote a Python recovery tool for stalled workers with dry-run output, a bounded batch size and operator approval; exercised it in staging before documenting production use.
Platform Engineer
Stonebridge Hosting
June 2020–January 2023
Reviewed Terraform changes for shared AWS infrastructure and added a rollback checklist covering state changes, service dependencies and the engineer responsible for approval.
Ran a Kubernetes restore exercise from a scheduled backup, checking a known scheduling record and recording elapsed recovery time and untested dependencies in the runbook.
Education
B.S. in Computer Science · Northvale College
August 2016–May 2020
Projects
Scheduling API indicator review
Site Reliability Engineer · Alder Relay Software
July 2025–September 2025
Prometheus · Grafana · Service review notes
Defined eligible request traffic and the observation window, then compared a Grafana availability panel with saved Prometheus queries. Documented that excluded health checks do not establish end-user success. The service owner approved the objective and the operations team used it to discuss release risk.
Distinguish objectives, incidents and verified recovery
Write the service-level indicator before the percentage. An availability statement needs an eligible request definition, a success rule, exclusions and an observation window. Marcus’s example defines a 30-day indicator; it does not claim an achieved uptime number. An SLO is the agreed target for a service. The measured result over a stated window is a separate fact.
Use an alert change to show operational judgment. Explain the symptom or budget signal, the action an on-call engineer can take, the test cases and the point at which paging was enabled. Fewer alert rules do not automatically mean less toil or fewer missed incidents. If you measured page volume, include equivalent periods and distinguish an actionable page from a notification.
Incident evidence should keep detection, customer-impact confirmation, mitigation and verified recovery distinct. A single incident timeline is useful even without a dramatic reduction in mean recovery time. Say what you coordinated, who owned technical fixes and how follow-up was tracked. A staging restore can demonstrate a practiced procedure, but untested production dependencies belong in the explanation.
Six annotated before-and-after bullets
These are teaching rewrites, not claims about real work. Preserve the setting, decision and ownership when adapting the pattern. If you cannot substantiate a number, explain an observed check or deliverable instead.
Define the denominator
Before: Delivered 99.99% uptime.
After: Defined the scheduling API availability indicator with the service owner as successful eligible requests divided by total eligible requests; documented health-check exclusions and the 30-day reporting window in Prometheus.
Defines what is measured and excluded. An objective is not an achieved reliability result.
Evidence to retain: Prometheus query, eligibility rules and service-owner agreement.
Show alert validation
Before: Eliminated alert fatigue.
After: Replaced duplicate symptom alerts with a reviewed multi-window error-budget alert and a runbook link; validated firing and recovery against replayed failures before enabling paging.
Explains an alert change and a test. It does not infer that paging volume or engineer wellbeing improved.
Evidence to retain: Alert rule, replay cases and runbook.
Separate incident intervals
Before: Reduced MTTR by 80%.
After: Coordinated the response to a queue backlog, recording detection, mitigation and recovery times; the review assigned follow-up owners for retry limits and queue-age monitoring.
A dated timeline is interpretable; a single incident cannot establish an average reduction.
Evidence to retain: Incident timestamps, review and follow-up owners.
Bound recovery automation
Before: Automated production recovery.
After: Wrote a Python recovery tool for stalled workers with dry-run output, a bounded batch size and operator approval; exercised it in staging before documenting production use.
Dry-run, batch limit and operator approval explain how the tool controls its scope.
Evidence to retain: Code review, staging exercise and operating instructions.
Show infrastructure judgment
Before: Managed cloud infrastructure.
After: Reviewed Terraform changes for shared AWS infrastructure and added a rollback checklist covering state changes, service dependencies and the engineer responsible for approval.
Links a concrete review to state and dependency risks without inventing change authority.
Evidence to retain: Terraform plan, reviewer comments and rollback checklist.
Limit the rehearsal claim
Before: Guaranteed disaster recovery.
After: Ran a Kubernetes restore exercise from a scheduled backup, checking a known scheduling record and recording elapsed recovery time and untested dependencies in the runbook.
A staging restore and a named validation are useful evidence but do not prove every production dependency.
Evidence to retain: Backup age, test record, elapsed times and unresolved dependencies.
Connect skills to inspectable work
Skill evidence in the fictional site reliability engineer record
Skill
Evidence to name
Sample connection
Indicators and objectives
Eligibility, numerator, denominator and reporting window.
The API availability indicator excludes health checks.
Alert design
Signal, action and replayed firing/recovery cases.
A reviewed budget alert links to a runbook.
Incident learning
Dated intervals, personal role and follow-up owners.
The queue review separates mitigation from recovery.
Automation
Scope limits, dry-run and approval.
The Python tool operates on bounded worker batches.
Recovery practice
Backup age, validation and untested dependencies.
A staging restore checks a known scheduling record.
KnowBe4 emphasizes cloud-native distributed-system reliability in a senior role. First Due combines platform operation, deployment and observability for fire and EMS software. Kalshi explicitly connects metrics, automation, incident response and work with product teams. Their overlap supports showing reliability decisions; it does not establish that every SRE uses the same cloud or owns the same production authority.
Connect reliability tools to a service and an operating decision
The summary names a scheduling service, AWS/Kubernetes, user-facing indicators and tested recovery procedures. The dated bullets show how Prometheus, Terraform and Python were used. This gives a reviewer a service context before a tool list. Avoid adding another cloud only because a vacancy mentions it if you cannot explain work performed there.
Keep the level of responsibility visible. Coordinating an incident is different from approving every remediation. Reviewing a Terraform plan is different from owning the infrastructure budget. Describe on-call or production access only when held, and state a real rotation scope if relevant. Do not share private customer incidents, exploitable configuration or internal service names in a public portfolio.
Use a rehearsal to demonstrate a first reliability project
Illustrative early-career adaptation
Summary: Computer-science graduate with a local scheduling-service project, container deployment and a documented failure exercise. Uses metrics and a runbook to explain detection and recovery steps.
Project bullet: Simulated a stalled worker in a local Kubernetes environment, recorded queue-age and request-success observations, and revised the recovery instructions after a classmate followed the runbook.
Boundary: A local exercise is valuable learning evidence. Label the environment and audience; it does not establish a production on-call rotation, customer impact, an organization-wide SLO or a contractual recovery promise.
Keep employment under its actual title and distinguish supervised work, independent projects and paid responsibility. A small, well-explained contribution is useful without adding an invented promotion or employer outcome.
List education and credentials with their actual status
List your actual degree and any held cloud or Kubernetes credentials with issuer and status. The cited employers differ in seniority and preferred qualifications. Marcus’s fictional degree is one path, and his recovery example is operating evidence rather than a certification. A training lab or an exam does not prove production access, incident command or compliance responsibility.
Check long contacts in Harbor with a photo
Only the contact email and one profile URL change in this version. The email uses a valid local part of at most 64 characters on example.com; the work, user identity, dates and projects match the base example. Compare the final characters with the complete text below and open the exported link. The longer strings test wrapping, not a recommended contact style.
Site reliability engineer supporting a multi-tenant scheduling service on AWS and Kubernetes. Defines user-facing indicators with service owners, improves alert actionability and writes tested recovery procedures. Keeps measured reliability, incident coordination and follow-up work separate so operational claims can be checked.
Defined the scheduling API availability indicator with the service owner as successful eligible requests divided by total eligible requests; documented health-check exclusions and the 30-day reporting window in Prometheus.
Replaced duplicate symptom alerts with a reviewed multi-window error-budget alert and a runbook link; validated firing and recovery against replayed failures before enabling paging.
Coordinated the response to a queue backlog, recording detection, mitigation and recovery times; the review assigned follow-up owners for retry limits and queue-age monitoring.
Wrote a Python recovery tool for stalled workers with dry-run output, a bounded batch size and operator approval; exercised it in staging before documenting production use.
Platform Engineer
Stonebridge Hosting
June 2020–January 2023
Reviewed Terraform changes for shared AWS infrastructure and added a rollback checklist covering state changes, service dependencies and the engineer responsible for approval.
Ran a Kubernetes restore exercise from a scheduled backup, checking a known scheduling record and recording elapsed recovery time and untested dependencies in the runbook.
Education
B.S. in Computer Science · Northvale College
August 2016–May 2020
Projects
Scheduling API indicator review
Site Reliability Engineer · Alder Relay Software
July 2025–September 2025
Prometheus · Grafana · Service review notes
Defined eligible request traffic and the observation window, then compared a Grafana availability panel with saved Prometheus queries. Documented that excluded health checks do not establish end-user success. The service owner approved the objective and the operations team used it to discuss release risk.
Read every page of the expanded site reliability engineer record
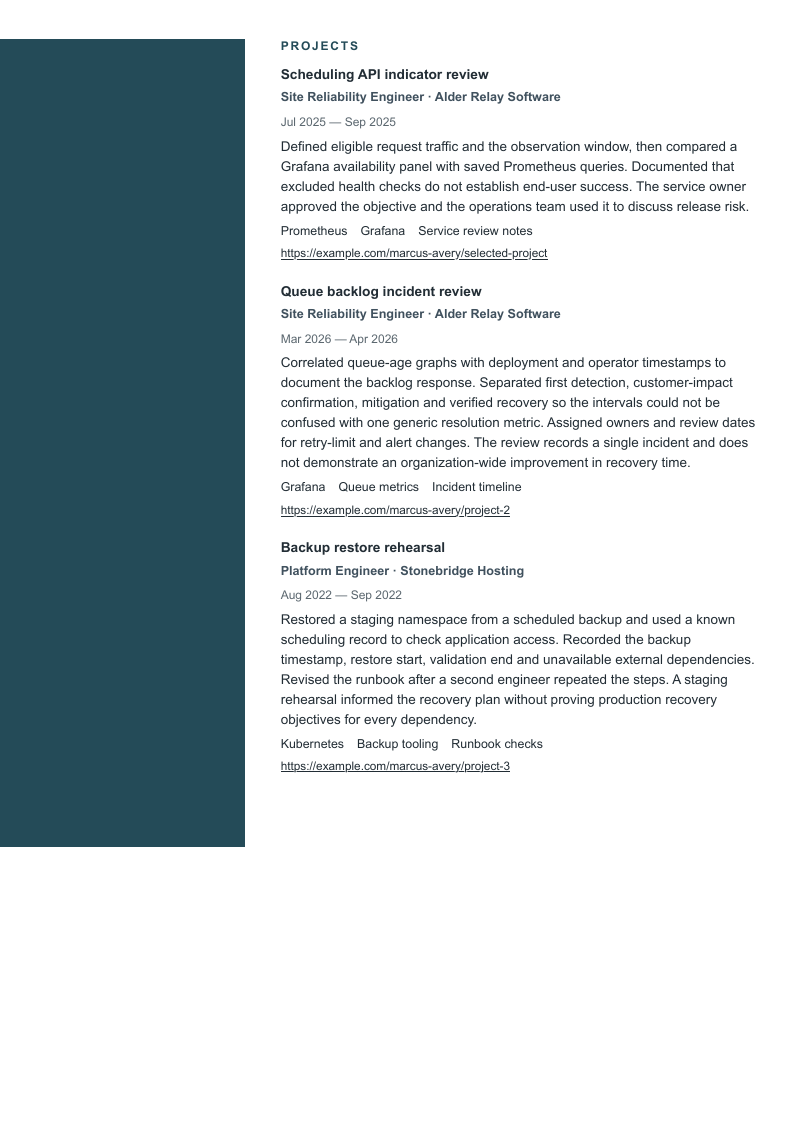
The expanded version preserves the base record and adds the earlier systems operations intern position plus two dated projects: Queue backlog incident review and Backup restore rehearsal. Each project uses the actual title and employer held on those dates. Harbor is shown without a photo. Check the final project sentence, earlier role and complete URLs across every page.
Site reliability engineer supporting a multi-tenant scheduling service on AWS and Kubernetes. Defines user-facing indicators with service owners, improves alert actionability and writes tested recovery procedures. Keeps measured reliability, incident coordination and follow-up work separate so operational claims can be checked.
Defined the scheduling API availability indicator with the service owner as successful eligible requests divided by total eligible requests; documented health-check exclusions and the 30-day reporting window in Prometheus.
Replaced duplicate symptom alerts with a reviewed multi-window error-budget alert and a runbook link; validated firing and recovery against replayed failures before enabling paging.
Coordinated the response to a queue backlog, recording detection, mitigation and recovery times; the review assigned follow-up owners for retry limits and queue-age monitoring.
Wrote a Python recovery tool for stalled workers with dry-run output, a bounded batch size and operator approval; exercised it in staging before documenting production use.
Platform Engineer
Stonebridge Hosting
June 2020–January 2023
Reviewed Terraform changes for shared AWS infrastructure and added a rollback checklist covering state changes, service dependencies and the engineer responsible for approval.
Ran a Kubernetes restore exercise from a scheduled backup, checking a known scheduling record and recording elapsed recovery time and untested dependencies in the runbook.
Systems Operations Intern
Stonebridge Hosting
June 2019–August 2019
Checked staging service health after supervised maintenance and recorded the commands and timestamps.
Updated a restart runbook after a colleague followed it during a practice exercise.
Education
B.S. in Computer Science · Northvale College
August 2016–May 2020
Projects
Scheduling API indicator review
Site Reliability Engineer · Alder Relay Software
July 2025–September 2025
Prometheus · Grafana · Service review notes
Defined eligible request traffic and the observation window, then compared a Grafana availability panel with saved Prometheus queries. Documented that excluded health checks do not establish end-user success. The service owner approved the objective and the operations team used it to discuss release risk.
Correlated queue-age graphs with deployment and operator timestamps to document the backlog response. Separated first detection, customer-impact confirmation, mitigation and verified recovery so the intervals could not be confused with one generic resolution metric. Assigned owners and review dates for retry-limit and alert changes. The review records a single incident and does not demonstrate an organization-wide improvement in recovery time.
Restored a staging namespace from a scheduled backup and used a known scheduling record to check application access. Recorded the backup timestamp, restore start, validation end and unavailable external dependencies. Revised the runbook after a second engineer repeated the steps. A staging rehearsal informed the recovery plan without proving production recovery objectives for every dependency.
This record exercises continuation pages; it does not prescribe a longer application. Select relevant work before shortening content for appearance. Keep the condition, responsibility or measurement definition needed to understand a bullet.
Check the final download before applying
Read every page at normal size, including the final bullet, project ending, qualifications and date ranges. Check contacts in both photo states.
Copy the PDF text into a plain document and inspect reading order across columns. Open each portfolio and project link and verify that it reaches material you may share.
Use the employer’s requested file format. Check fields populated after upload; a clean visual preview cannot guarantee parsing in every system.
Verify titles, dates, measurement definitions and personal contribution. Replace all fictional details and remove private employer or customer information.
Review your site reliability engineer resume with the analyzer and judge suggestions against evidence you can support. The Use buttons retain the selected design and photo preference through signup; an account is required. Free-plan PDF downloads include a watermark, while these previews show paid-plan output.
Questions, answered
Should I put an uptime percentage in my summary?
Only when you can define the service, measurement method, period and your contribution. An SLO target is not achieved availability. A precise explanation of indicator design can be stronger than a percentage without a denominator.
How should I describe MTTR?
Define what the acronym means in your organization and the start and end events. Give the incident population and comparable periods if reporting an average or improvement. A single fast recovery does not establish a lower mean.
Is on-call experience required for every SRE position?
Read the specific description. If you held a rotation, report its scope accurately and describe an operating decision. A practice exercise or production-support course should remain clearly labeled.
Can I use a home lab on an SRE resume?
Yes, when the environment, generated workload and failure scenario are explicit. Show observations, the recovery procedure and what remains untested. Do not present local traffic or a classmate walkthrough as customer production evidence.
How much incident detail belongs in a public portfolio?
Use approved or synthetic material, describe the method and your role, and omit sensitive customer, credential or infrastructure information. An anonymized decision and follow-up process can explain the work without publishing internal operational records.
Does signup retain the chosen design and photo preference?
The Use buttons pass that exact design and current photo preference through signup to the builder. An account is required. The fictional resume and portrait are not inserted into your account. Free-plan PDF downloads include a watermark; the displayed previews show paid-plan output.
Prepared by Resumize with AI-assisted research and drafting for English-language US applications. Three primary employer descriptions with full bodies and application forms were checked on October 29, 2026; publication dates were not shown and availability can change. Occupation and resume guidance below inform scope and presentation. The fictional resume, annotated rewrites and critiques are original editorial examples, not employer endorsements. No Search Console data, search-volume estimate or ranking forecast was available.
Checked October 29, 2026: full description and application form available; publication date not shown. Remote US only. Distributed systems, automation and cloud reliability; senior experience and preferred certifications are vacancy-specific.
Checked October 29, 2026: full description and application form available; publication date not shown. Remote US only. Infrastructure, deployment, observability and incident improvement for fire and EMS software.
Checked October 29, 2026: full description and application form available; publication date not shown. New York. Defines reliability metrics, reduces toil and works with infrastructure and product teams; financial-system context is employer-specific.